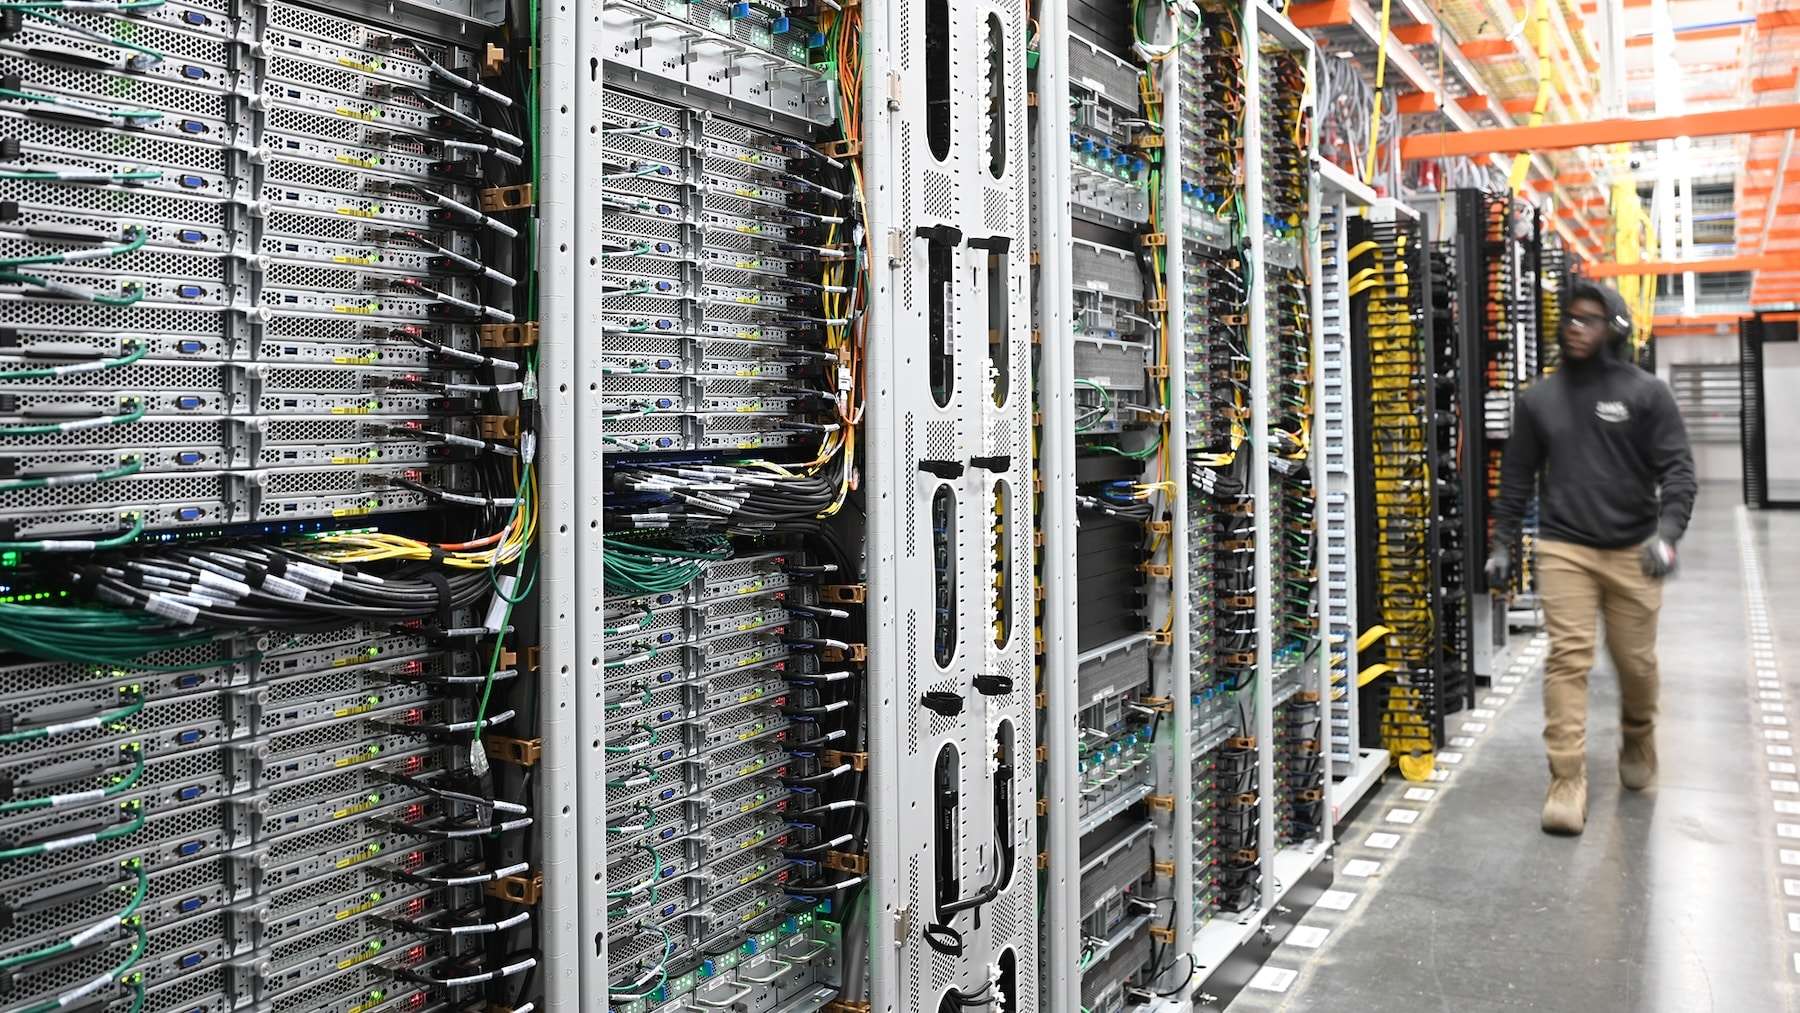
Drone attacks on data centers in Russia and the damage suffered by Amazon Web Services (AWS) facilities in the Middle East have exposed a vulnerability that affects governments, businesses, and individual users alike: storing files in the cloud doesn’t mean they’re safe from every kind of disaster. When a facility loses its servers, power, or cooling systems, the consequences can extend to applications, payments, AI services, and data that thousands of organizations use every day.
Data centers under attack in 20 seconds
- In October 2026, three Yandex data centers suffered drone attacks in different regions of Russia and were left fully or partially out of service.
- In March, AWS confirmed damage to three facilities in the United Arab Emirates and Bahrain following drone attacks.
- Having multiple copies isn’t enough if they all depend on the same region, account, or provider.
- Users and businesses can reduce the risk with independent copies, restore tests, and plans for operating during an extended outage.
The cloud can feel intangible: you upload documents, photos, databases, or applications and access them from anywhere. But behind every service there are buildings, servers, communications networks, power supplies, cooling systems, and technical staff. A serious disruption to any of those elements can make information inaccessible or destroy part of it.
Military attacks aren’t the only risk. A fire, a flood, a configuration error, a ransomware attack, or an account suspension can also cut off access to data. The difference is that a physical attack can simultaneously affect the equipment, communications, and recovery systems located at the same site.
The practical lesson isn’t to abandon cloud services, but to stop relying on a single copy or a single path to recover information.
From Yandex to AWS: when physical damage disrupts digital services
Between October 8 and 11, three Yandex data centers were affected by drone attacks in the Russian regions of Ryazan, Kaluga, and Vladimir. The company confirmed the shutdown of its Sasovo facility, partial damage in Kaluga, and disrupted operations in Vladimir. The incidents affected several of the company’s services, including its cloud platform, its mobility apps, and its payment system.
Yandex warned its customers that its platform was running in emergency mode and recommended turning to the alternative recovery plans available. The incident shows that having multiple facilities doesn’t guarantee continuity if several sites are damaged within a short time frame, or if the remaining capacity can’t absorb all the demand.
The precedent from the Middle East is equally relevant. In March 2026, AWS confirmed that two data centers in the United Arab Emirates had taken direct hits and that a third facility in Bahrain had been affected by a nearby attack. The company reported structural damage, power outages, and water damage related to firefighting efforts. AWS has since told affected Gulf customers to migrate their workloads to other regions, months after the incident.
The consequences reached services hosted in the affected AWS region. The specific impact depended on each customer’s architecture, the services used, and whether alternative resources were available. It doesn’t mean that all data stored on AWS was lost, or that all of the company’s services were disrupted.
Nor should an application’s availability be confused with the permanent loss of its data. A service can stop responding because its servers are offline, even though the information is still stored on recoverable media. In other cases, physical damage, a lack of replicas, or the inability to access backups can make recovery far more difficult.
The two episodes show why infrastructure location matters. A company can hire a global provider and still keep all its critical systems in a single region, or concentrate its backups in facilities exposed to the same incident.
What a user should do to avoid losing their files
For an individual, the first step is to distinguish between syncing and backing up. Services like Google Drive, OneDrive, Dropbox, or iCloud let you access the same files from different devices, but syncing can also propagate unwanted deletions or changes. If a file disappears from the synced folder, the change can replicate to other devices, although some services keep previous versions or a trash folder for a limited time.
An independent copy lets you recover documents without relying solely on that sync. You don’t need to build a professional system to protect photos, personal documents, or work files, but it’s worth keeping a second copy outside the main service.
A simple approach for personal files:
- Keep files in the cloud to access them from your phone, computer, or any other device.
- Make a periodic backup to an external drive, connected only while the backup runs whenever possible.
- Keep a second copy in another location, for example on another device or in a different storage service.
- Check that the files can actually be opened and that the backup really contains the important folders.
- Store recovery codes and emergency credentials in a safe place, separate from your main device.
The 3-2-1 backup rule sums up a widely used strategy: keep three copies of the information, counting the original, use two different types of storage media, and keep at least one copy away from the main location. It’s not an absolute guarantee, but it reduces reliance on a single device, building, or system.
For especially sensitive files, it’s worth encrypting the backups and protecting them with credentials different from those of the main account. An external drive that stays permanently connected to the computer offers less protection against certain cyberattacks than one that remains disconnected when not in use. It’s also advisable to enable multi-factor authentication on the accounts that store the files.
The goal is to ensure that a provider outage, the loss of a computer, or an account lockout doesn’t mean losing every available version.
The contingency plan a business needs
At a company, losing access to data can halt billing, customer service, logistics, financial operations, or employees’ work. That’s why the plan shouldn’t be limited to purchasing extra cloud storage. It needs to specify what gets recovered first, how long each service can stay down, and how much information can be lost at most.
Two concepts help translate those needs into technical decisions:
- RTO (Recovery Time Objective): the maximum time the organization accepts to recover a service after a disruption.
- RPO (Recovery Point Objective): the maximum amount of recent data the organization accepts losing, expressed as the time elapsed since the last recoverable point.
An internal-use application might tolerate several hours of downtime. A payments platform or an order-management system may need to recover much sooner. Likewise, a daily backup may be enough for documents that change rarely, but not for a database that logs transactions continuously.
The strategy needs to match those differences. Not every application needs an active replica in another region — a solution that can significantly raise costs and complexity. For some systems, automated backups and a proven recovery process will be enough. For others, it will be necessary to keep infrastructure ready in an alternate location.
A practical guide for organizations includes these measures:
1. Identify critical data and services. You need to inventory databases, documents, source code, applications, identity systems, configurations, and external dependencies. It’s also worth documenting which services need to be recovered first and who can authorize emergency decisions.
2. Keep backups separate from the production environment. Backups shouldn’t rely solely on the same account, the same credentials, or the same infrastructure as the original systems. A backup protected against unauthorized deletions and administrative access reduces the risk of a single incident affecting everything.
3. Keep backups outside the main region. Replicating data between availability zones can protect against certain local failures, but it’s not the same as having a recovery plan for the loss of an entire region. To cover that scenario, you need to look at an alternate location and check which services can be rebuilt there.
4. Keep versions and immutable backups when necessary. Continuous replication keeps several locations up to date, but it can also propagate an accidental deletion or corruption. Historical versions and backups that can’t be modified for a set period make it possible to roll back to an earlier state.
5. Also back up what’s needed to rebuild the service. Data alone isn’t enough. Recovery can require code, configurations, securely managed keys, machine images, documentation, infrastructure as code, and procedures for deploying the systems.
6. Test the restore process. A backup job marked as completed doesn’t prove that every file is intact or that an application can come back online. Periodic tests should measure how long it takes to recover the data and confirm that the service returns to operation within the set targets.
7. Prepare an operational fallback. If the main platform is unavailable, the company needs to know how to serve customers, log orders, communicate incidents, and keep priority operations running. In certain sectors, temporary manual procedures may be necessary.
8. Define who decides and how it’s communicated. The plan needs to identify the people responsible, alternative communication channels, and the criteria for triggering recovery. If corporate email or collaboration tools also depend on the affected service, an independent channel is needed.
Is it enough to contract two cloud providers?
Not necessarily. Having two contracts doesn’t guarantee that applications can move from one to the other. There can be dependencies on databases, proprietary services, incompatible formats, identity systems, or transfer limits that complicate recovery.
A multicloud strategy can reduce dependence on a single provider, but it also requires maintaining and testing two environments. For many companies, a combination of independent backups, external storage, and rebuild procedures is more realistic than duplicating the entire infrastructure. This is also why a backup that can survive an attack on the production systems matters as much as the attack vector itself, as the Telemadrid ransomware case showed.
It’s also worth reviewing the contract terms, the recovery times the provider offers, and the actual location of the data. The term “high availability” can refer to continuity against certain failures, not necessarily survival in the event of the simultaneous loss of several data centers or an entire region.
The cost of contingency planning should be weighed against the impact a disruption would have. Not all data needs the same level of protection, but the systems that sustain business activity need explicit recovery targets and tests that prove they’re achievable.
The cloud is still useful, but recovery can’t be taken for granted
Data centers offer economies of scale, the ability to expand capacity, and services that would be difficult for an organization to maintain on its own. Using them doesn’t mean data is permanently exposed, or that a military attack will necessarily cause widespread loss. Providers operate with redundancy and recovery mechanisms, though their scope depends on the architecture a customer has set up and how they use it.
The 2026 incidents show, however, that protecting physical infrastructure is part of digital continuity. Backups located in the same region may not be enough in the face of a regional disaster; replication doesn’t always protect against corruption; and having a backup doesn’t guarantee there’s a procedure capable of restoring it in time.
For an individual user, an external copy that’s updated and checked regularly can make a real difference. For a business, the extra step is deciding how long each system can stay down, how much data loss is acceptable, and how the business will recover if its main provider fails.
The likelihood of a military attack will depend on the country, the location, and the type of infrastructure. But the same plan also helps against power failures, fires, human error, cyberattacks, or provider issues. Preparing for those scenarios doesn’t require assuming they’ll happen tomorrow; it requires making sure a single incident can’t wipe out the only available copy.
Frequently asked questions
Can files stored in the cloud be lost in a military attack?
Yes, an attack could destroy infrastructure or leave data inaccessible. The outcome depends on whether recoverable copies exist in other locations and how the service is designed.
Do Google Drive, OneDrive, or Dropbox replace a backup?
Not always. Syncing keeps files up to date across devices, but it can also propagate deletions and changes. An independent copy provides another way to recover.
What is the 3-2-1 backup rule?
It means keeping three copies of the data, counting the original, using two different types of storage media, and keeping at least one copy away from the main location. It’s a guideline for reducing dependence on a single system.
What should a company’s contingency plan include?
It should identify critical systems, define acceptable recovery times and data loss, keep independent backups, document how to rebuild services, and periodically test the restore process.
