AI infrastructure is starting to split into two very different acquisition models. Thinking Machines Lab has signed a $65 million-a-year deal with Crusoe to run managed inference on a dedicated NVIDIA HGX B200 deployment, while Anthropic is holding early talks to lease up to 1 gigawatt (GW) directly from Stream Data Centers. The contrast points to an increasingly relevant question: when does it make more sense to buy capacity as a service, and when does an AI company need to control a larger share of the infrastructure itself?
Thinking Machines and Anthropic’s AI infrastructure moves in 20 seconds
- Thinking Machines Lab will pay Crusoe $65 million a year for managed inference.
- The deployment uses NVIDIA HGX B200 systems and Quantum-2 InfiniBand networking.
- Anthropic is exploring leasing up to 1GW directly from Stream Data Centers.
- Anthropic’s deal is still under discussion and its structure isn’t finalized.
- Both moves show how AI labs are increasingly splitting apart inference, training, chips, data centers, and financing.
The contrast is worth noting because neither company is buying exactly the same thing. Thinking Machines Lab is contracting a dedicated inference service: Crusoe operates the cluster, maintains the infrastructure, and delivers an access point with service conditions. Anthropic, according to talks reported by The Information, is reportedly considering becoming a direct tenant of Stream Data Centers facilities and controlling a larger share of the physical capacity it uses.
The difference matters because inference has a characteristic that sets it apart from training. Once a model reaches production, it needs continuous compute capacity to respond to user requests. Cost stops being concentrated solely in large training runs and shifts to the day-to-day operation of the models as well.
Thinking Machines buys inference as a service
The deal announced by Crusoe on September 23 totals $65 million a year and covers Thinking Machines Lab’s production inference workloads. Models that will run on it include the lab’s own Inkling models, GLM 5.2 and 5.3, and variants fine-tuned by the company itself.
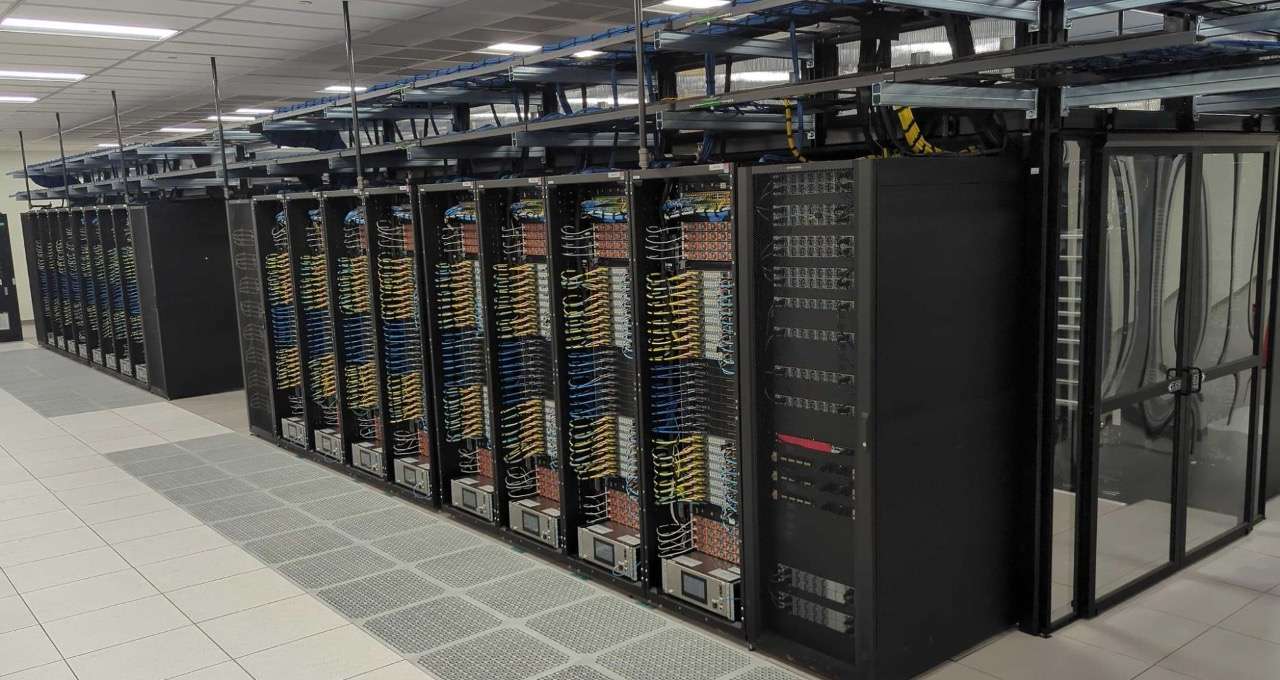
The infrastructure will consist of a dedicated NVIDIA HGX B200 deployment, connected via NVIDIA Quantum-2 InfiniBand. Crusoe calls it a Tailored Deployment, a dedicated configuration backed by a service-level agreement (SLA) that the company operates directly.
That shifts the customer’s responsibility. Thinking Machines Lab doesn’t need to directly handle setting up servers, operating the accelerator network, or maintaining the inference platform. Crusoe takes on that part, and the lab consumes the resulting capacity.
The company has also said it’s exploring extending the service to batch inference for synthetic data generation, a different scenario from handling real-time user requests.
For Crusoe, the deal also means its Managed Inference business now exceeds $100 million in contracted annual recurring revenue, according to the company itself. The service had been on the market for less than a year.
The model is attractive when a lab wants dedicated capacity and predictable performance but doesn’t want to take on the entire physical and software operation that sits underneath an inference service. NVIDIA GPU deployments like Crusoe’s aren’t unique in the market either — AMD has previously backed a $300 million loan to help Crusoe deploy its own AI chips, a sign of how much capital is flowing into financing this kind of dedicated AI capacity.
Anthropic is exploring another path to a gigawatt
Anthropic’s move is different and, for now, should be treated as a preliminary negotiation. The Information reported that the company is in talks to lease up to 1GW of compute capacity from Stream Data Centers, a data center developer majority-owned by Apollo Global Management.
The reporting indicates Anthropic could become a direct tenant of the facilities and that accelerators from different vendors could be used there. Among the possibilities mentioned are tensor processing units (TPUs) designed by Google and Broadcom, though NVIDIA GPUs or other AI chips could also be used. Google has reportedly also considered offering some kind of financial guarantee for the project, though the scope of that potential guarantee isn’t defined.
The scale completely changes the nature of the deal. According to estimates gathered by The Information, a 1GW deployment could require at least $40 billion in investment. That means an operation of this size doesn’t depend solely on securing chips: it also needs financing, facilities, power, networking, cooling, and long-term contracts.
Anthropic already has large-scale agreements with infrastructure providers, including a platform it created with GIC and Macquarie Asset Management to secure the physical infrastructure Claude needs. In April, the company announced a commitment worth more than $100 billion over ten years with Amazon for AWS technologies and up to 5GW of capacity based on current and future generations of Trainium. Anthropic has also said it uses a mix of AWS, Google, and NVIDIA hardware.
In May, the company also announced a deal with SpaceX to use more than 300MW of capacity at the Colossus 1 data center, alongside agreements with Google and Broadcom, Microsoft and NVIDIA, and other providers.
That’s why a possible deal with Stream wouldn’t mean Anthropic is abandoning the cloud. It would fit instead into a strategy of diversification and greater direct control over physical capacity — a strategy the company has also pursued on the chip side, having confirmed last year that it’s building its own silicon engineering team.
Infrastructure is starting to look like a financial operation
As deployments grow from hundreds of megawatts to gigawatts, buying compute stops being solely a decision about which GPU to use.
An AI data center needs to secure land, a power connection, generation or grid capacity, cooling systems, servers, accelerators, high-speed networking, and financing. It also needs contracts that justify the investments over several years.
That explains why structures are emerging in which real estate developers, chipmakers, infrastructure providers, banks, funds, and large AI customers can all take part in a single deal.
The market is already using financial mechanisms to spread that risk. The Financial Times reported this week that companies like NVIDIA, Broadcom, and Meta are using guarantees on the residual value of chips and data centers to back financing tied to AI infrastructure, with up to $300 billion in credit exposure linked to these structures.
Not all these deals share the same structure, but they share one problem: AI compute capacity requires enormous upfront investment, and the assets need to be financed before they generate revenue over their entire useful life.
That’s where the difference between the two cases shows up. Thinking Machines Lab is shifting a significant part of that work onto Crusoe. The lab pays for dedicated inference capacity, and Crusoe handles the underlying infrastructure.
Anthropic, on the other hand, appears to be moving toward greater direct involvement in acquiring physical capacity. The possible contract with Stream isn’t finalized yet, so it can’t be said the company will ultimately control 1GW or what hardware will end up installed.
The trend both moves point to is more concrete: AI infrastructure is being unbundled. Training and inference can be contracted in different ways; chips can come from different manufacturers; data centers can be owned by third parties; and financing can be structured separately from the compute contract.
For labs operating large-scale models, that flexibility can matter as much as any single accelerator’s performance. The question is no longer just how many GPUs a model needs, but who finances the data center, who operates the servers, who takes on the capacity risk, and how much of the infrastructure the customer wants to control directly.
Frequently Asked Questions
How much will Thinking Machines Lab pay Crusoe?
The deal announced on September 23 totals $65 million a year to run production inference workloads through Crusoe Managed Inference.
What hardware will Thinking Machines Lab use?
The workloads will run on a dedicated deployment of NVIDIA HGX B200 systems connected via NVIDIA Quantum-2 InfiniBand. Crusoe will operate the cluster directly.
Has Anthropic already signed the 1GW deal with Stream Data Centers?
No. The available information points to preliminary talks to lease up to 1GW of capacity. The structure, final volume, and hardware haven’t been finalized yet.
Why does Anthropic want to directly control more infrastructure?
A possible deal would give Anthropic a more direct relationship with data center facilities and compute capacity. The company also maintains large agreements with AWS, Google, NVIDIA, Microsoft, and other providers, so the move fits with a strategy of diversified capacity.
